The task
Solve a known algorithm problem
Fix a bug, add a feature or improve a design in an existing codebase
We give candidates a real work task, they complete it, then answer questions about how they solved it. You get a simple report telling you if they’re ready to do the job.

 Engineering roundEngineering
round
Solve a known algorithm problem
Fix a bug, add a feature or improve a design in an existing codebase
An empty editor
A real, working project, set up the way your team’s is
Input and expected output
A PM document or a customer ticket, with the business rules and reference tables
Blocked, and any model still solves it in seconds
Allowed, expected and measured
Test cases pass or fail
Hidden suite, code quality, an interview on their own code, and how they used AI
Whether the fundamentals are there
Whether they can ship production work, and how they use AI while doing it
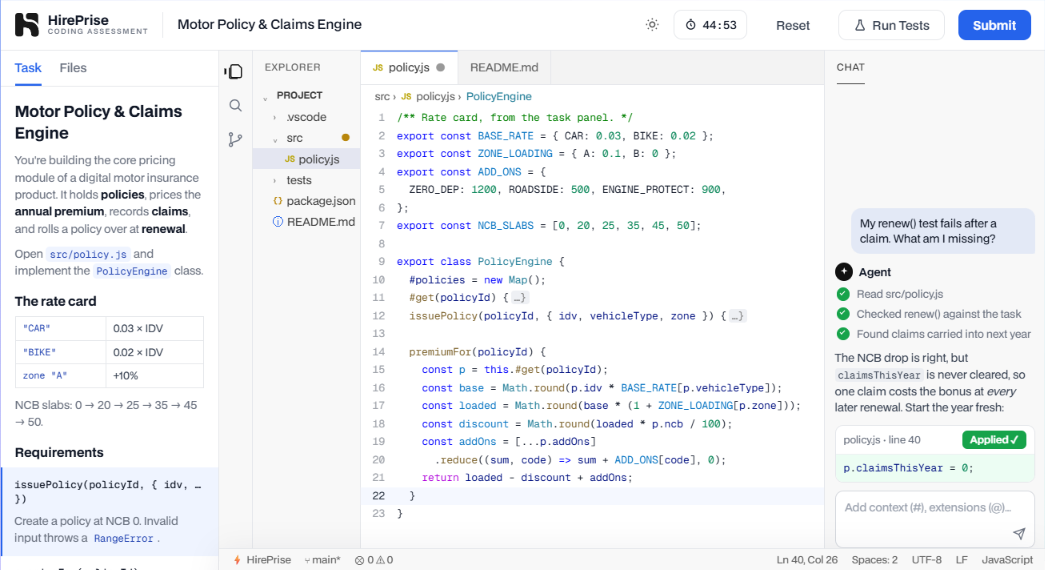
The task arrives the way work does: a product brief with business rules and acceptance criteria, or a ticket raised by a customer. It lands in a working project, not an empty editor, and reading it carefully is part of the test.
A chat panel with agent mode and plan mode. Candidates are expected to use it, and the report shows what they asked, when they asked it, and how much of the output they rewrote by hand.
Sample tests run in the IDE while they work, so they get the same feedback loop they would get at their desk. A hidden suite grades the submission.
“A strong candidate who works with AI deliberately rather than blindly. Planned before building, drove the solution with a tight test loop, and committed in reviewable increments.”
HirePrise · engineering round
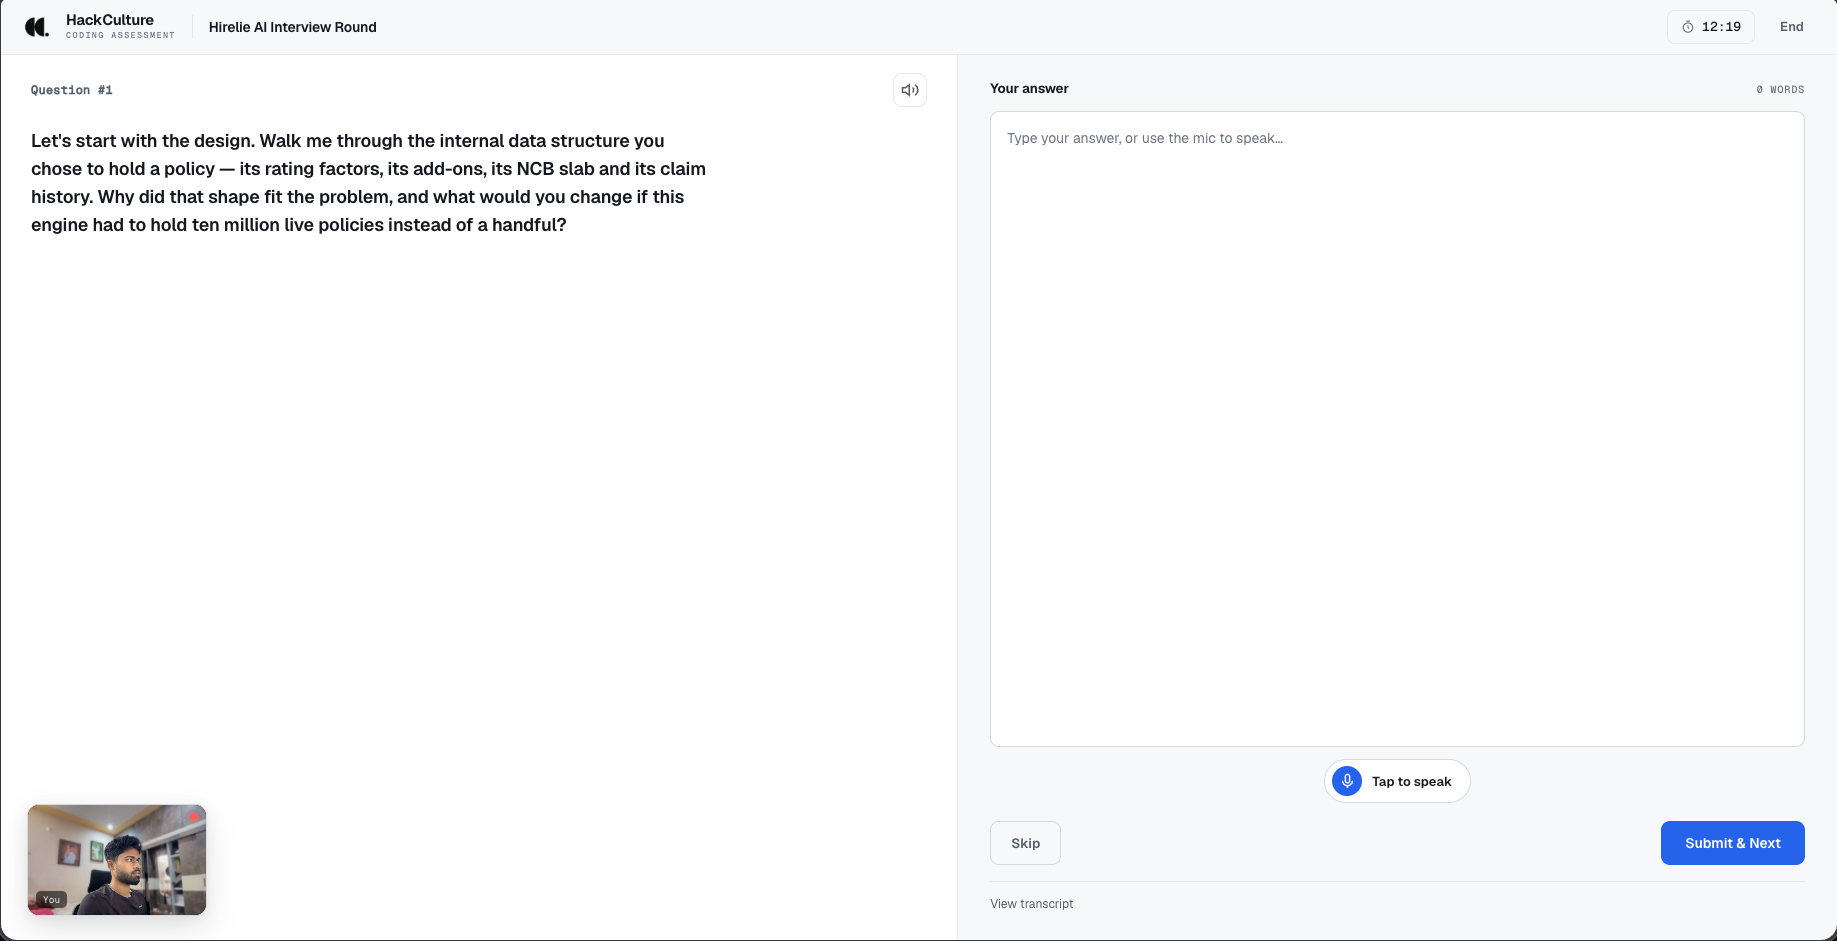
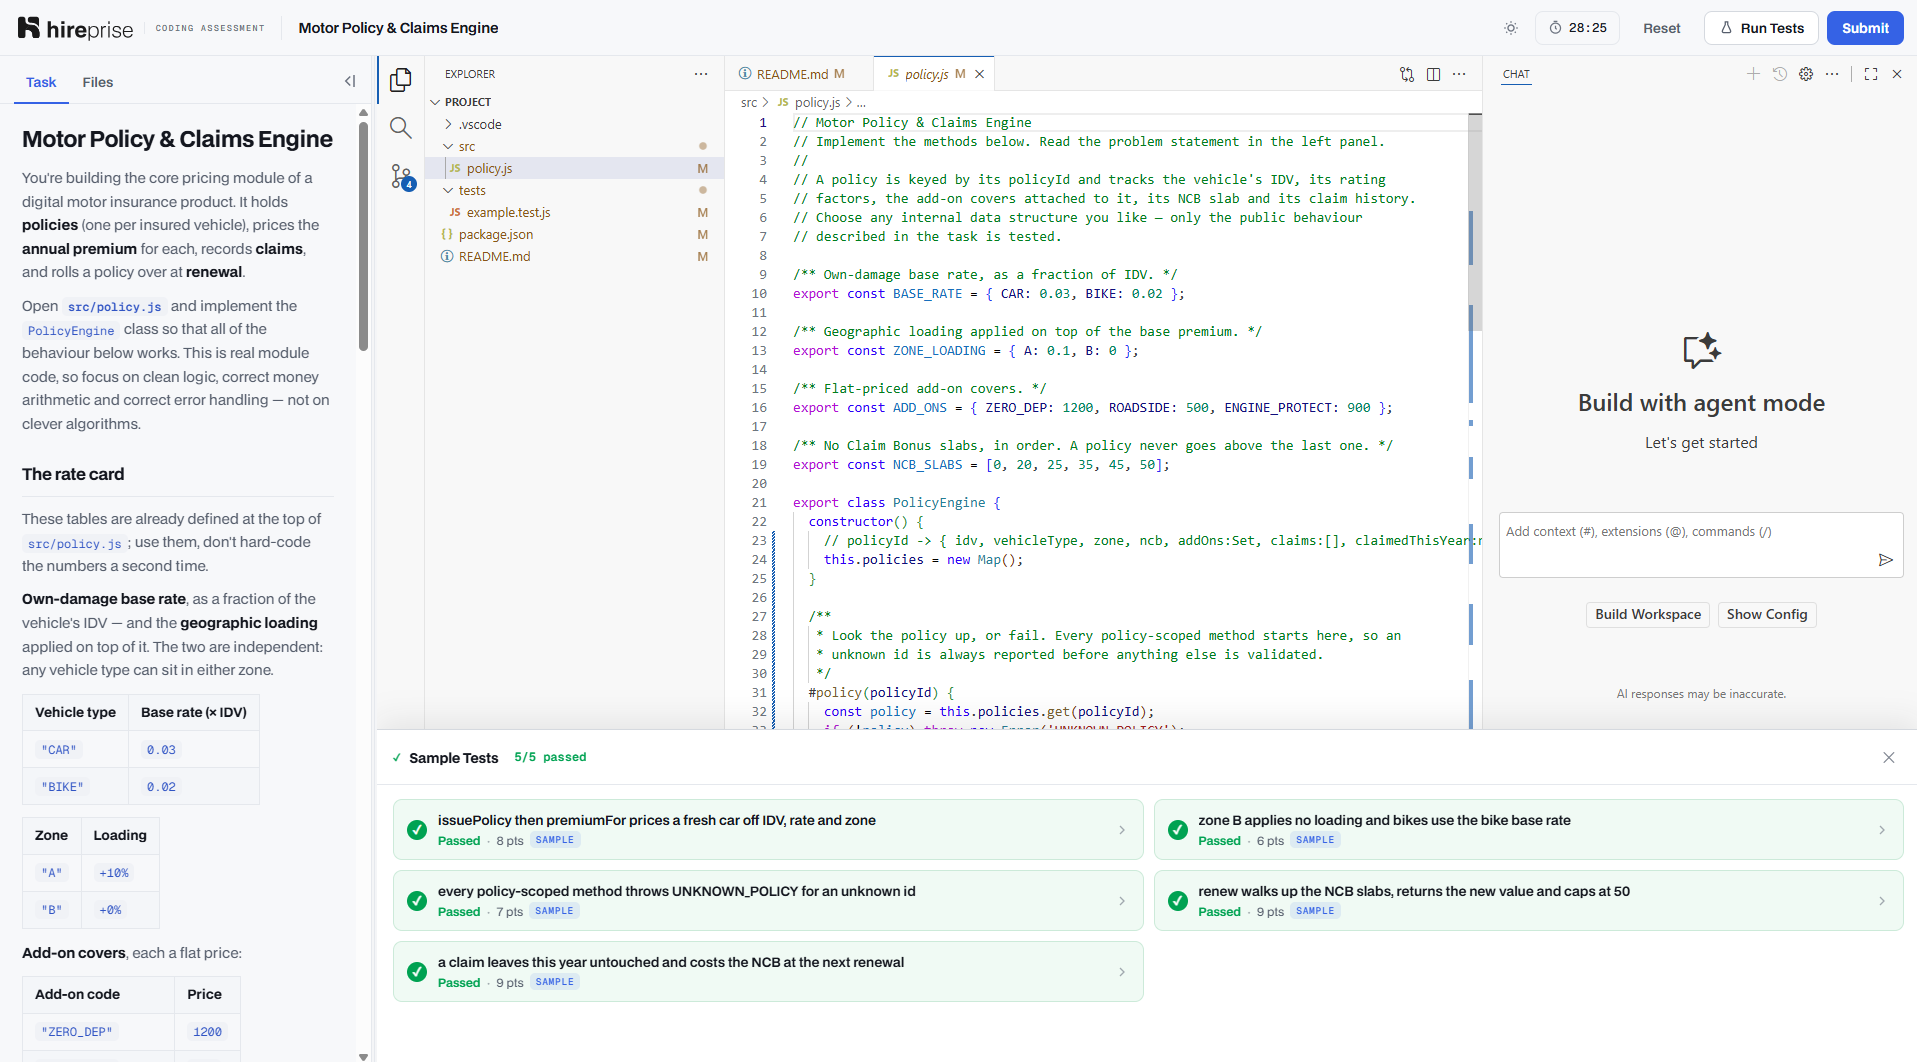
Yes. AI is allowed, expected and measured. Every prompt in the session is captured, so the report shows how they used the agent, not just whether they did.
The task sits inside a working project, and the round ends with an interview generated from the diff they just submitted. Nothing can be rehearsed, and a hidden test suite grades the code they actually shipped.
You set the duration when you configure the round, so it can match the role and the task. Whatever you pick, it is one timed session: read the PM brief, work in the repo, run the sample tests, submit. The interview and the report follow straight after.
Nothing. The workspace runs in the browser with an editor, a terminal, sample tests and an agent panel — the same loop they already work in.
The hidden suite score, code quality, the interview on their own code, and how they used AI. Every claim points back to a prompt, a commit or a failing test in the session.
Run either, or both. The DSA round tells you whether the fundamentals are there; the engineering round tells you whether they can ship production work and how they use AI while doing it.
Yes. Screening rounds, campus drives and senior loops all run through the same pipeline and are graded the same way every time, so results stay comparable across the funnel.
Book a call. We walk your team through a live assessment and a real candidate report in thirty minutes.
We walk your team through a live assessment and a real candidate report. Thirty minutes.
See a sample report
Tell us where to send it. We ask for a company email so we know which team is looking.
Book a call